Data Ingestion Tools Comparison
There are two main ways to get data out of an SAP ERP system reliably:
1. Environments, setup
Run options
How is the tool installed and operated
- SaaS: multitenant application managed by the tool provider
- on-prem: application installed inside the client’s environment and managed by the client
- agent: a small piece of software installed inside the client’s environment designed to process and send (push) data into the target cloud space
Installation needed:
What needs to be installed inside the client’s environment
- some type of an agent
- full app installation
- no installation is needed (full SaaS)
2. Costs
Pricing
How each tool is priced.
- consumption-based
- no of pipeline runs, per hour of run
- number of active pipelines
Tiers
- pay-as-you-go (you pay for every pipeline, GB, minute of run, …)
- tiered packages (250 pipelines, 500 pipelines, 1000 pipelines)
Free of additional costs
Does the tool require additional computing (HW/VMs) to be used?
3. Historical SAP data extraction
4. Continuous SAP data extraction
Real-time support
Does the tool support (near) real-time data ingestion?
- real-time (<1s)
- near real-time (~1 - 5s)
- micro-batches (e.g. every 5+ minutes)
SAP Extractors, CDS Views support
Is the tool capable of connecting to standard higher-level SAP data extraction interfaces provided by ECC or S/4?
- BW Extractors (via ODP/SAPI)
- CDSViews - new extraction interface for SAP S/4
- Stream tables
- Custom ABAP Extractors - Business Logic, ABAP API, Function Module etc.
BW data extraction support
Is the tool capable of connecting to standard higher-level SAP data extraction interfaces in BW?
- InfoProviders - DSOs, ADSOs, Cubes
- InfoObjects
- HANA Calculation Views
- BEx Queries
- RAW tables
New records (deltas) processing for CDSViews/HANA Calculation views
Does the tool have the ability to process new records only from CDSViews or HANA Calculation views or does it always require full load?
5. Writing data to target
Schema conversion
Are the data and associated column types ingested from SAP converted into Databricks-compatible column types?
DeltaLake support
Is the data ingestion tool capable of writing data in the Databricks Delta format into the landing zone of the data lake?
How does the incoming data processing work?
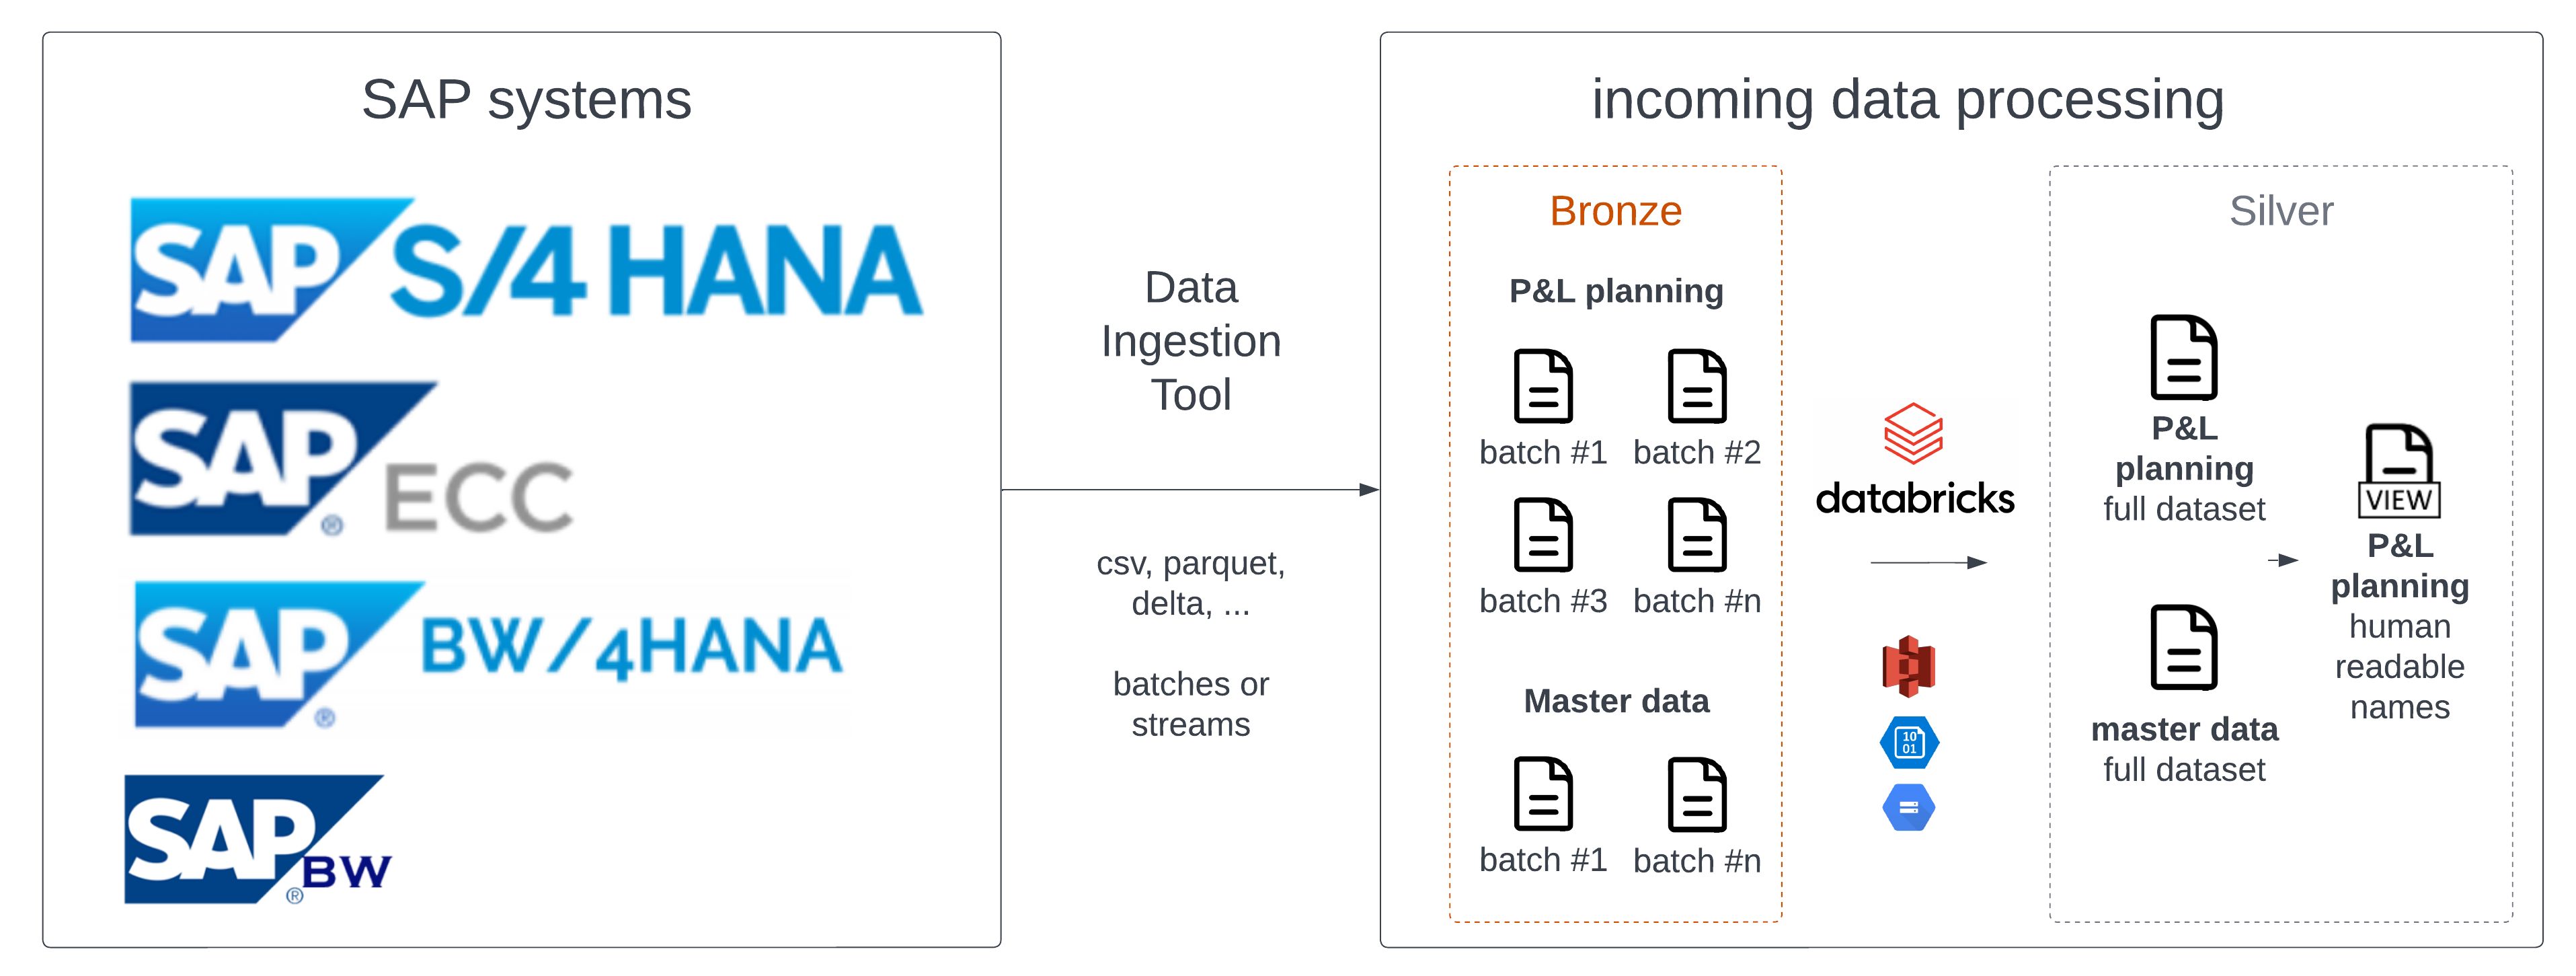
The data ingestion tool generates smaller (real-time/micro-batching) or larger (hourly/daily processing) batches of data that are written into CSV, parquet, delta or some other format and then written into the cloud storage (AWS S3, Azure Blob Storage, GCP Cloud Storage).
As soon as the file (P&L planning data of the diagram) lands in the bronze/landing zone of the data lake, Databricks can pick the file and append it to the overall P&L planning table stored in the silver layer.